Jaemin Cho
Jaemin Cho
News
Group
Teaching
Talks
Publications
1
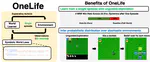
One Life to Learn: Inferring Symbolic World Models for Stochastic Environments from Unguided Exploration
OneLife learns symbolic programmatic world models from a single episode of unguided exploration in stochastic environments
Zaid Khan
,
Archiki Prasad
,
Elias Stengel-Eskin
,
Jaemin Cho
,
Mohit Bansal
Preprint
Cite
Project
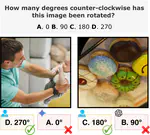
RotBench: Evaluating Multimodal Large Language Models on Identifying Image Rotation
a benchmark evaluating MLLMs’ ability to identify image rotation
Tianyi Niu
,
Jaemin Cho
,
Elias Stengel-Eskin
,
Mohit Bansal
Preprint
Cite
Code
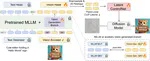
Bifrost-1: Bridging Multimodal LLMs and Diffusion Models with Patch-level CLIP Latents
a unified framework that bridges multimodal LLMs and diffusion models with patch-level CLIP latents
Han Lin
,
Jaemin Cho
,
Amir Zadeh
,
Chuan Li
,
Mohit Bansal
Preprint
Cite
Code
Project
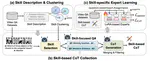
Video-Skill-CoT: Skill-based Chain-of-Thoughts for Domain-Adaptive Video Reasoning
a framework that automatically constructs and leverages skill-aware CoT supervisions for domain-adaptive video reasoning
Daeun Lee
*,
Jaehong Yoon
*,
Jaemin Cho
,
Mohit Bansal
Preprint
Cite
Code
Project
CAPTURe: Evaluating Spatial Reasoning in Vision Language Models via Occluded Object Counting
a VLM benchmark testing spatial reasoning by making the models count objects under occlusion
Atin Pothiraj
,
Elias Stengel-Eskin
,
Jaemin Cho
,
Mohit Bansal
Preprint
Cite
Code
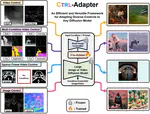
Ctrl-Adapter: An Efficient and Versatile Framework for Adapting Diverse Controls to Any Diffusion Model
A plug-and-play framework that reuses any existing ControlNet for any video/image diffusion model
Han Lin
*,
Jaemin Cho
*,
Abhay Zala
,
Mohit Bansal
Preprint
Cite
Code
Project
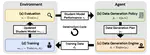
DataEnvGym: Data Generation Agents in Teacher Environments with Student Feedback
A new testbed of teacher environments for data generation agents for diverse tasks.
Zaid Khan
,
Elias Stengel-Eskin
,
Jaemin Cho
,
Mohit Bansal
Preprint
Cite
Code
Project
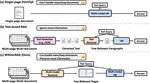
M3DocRAG: Multi-modal Retrieval is What You Need for Multi-page Multi-document Understanding
Multi-modal RAG framework and dataset for multi-page multi-document understanding
Jaemin Cho
,
Debanjan Mahata
,
Ozan İrsoy
,
Yujie He
,
Mohit Bansal
Preprint
Cite
Code
Project
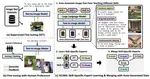
SELMA: Learning and Merging Skill-Specific Text-to-Image Experts with Auto-Generated Data
SELMA improves T2I models by fine-tuning on automatically generated multi-skill image-text datasets, with skill-specific LoRA expert learning & merging. -
NeurIPS 2024
Jialu Li
*,
Jaemin Cho
*,
Yi-Lin Sung
,
Jaehong Yoon
,
Mohit Bansal
Preprint
Cite
Code
Project
DiagrammerGPT: Generating Open-Domain, Open-Platform Diagrams via LLM Planning
Using LLM (GPT-4) to generate a ‘diagram plan’ for fine-grained layouts (object/text labels/arrows, etc.) and render in either raster images (via diffusion) and vector graphics (via PowerPoint / Inkscape or any tools). -
COLM 2024
Abhay Zala
,
Han Lin
,
Jaemin Cho
,
Mohit Bansal
Preprint
Cite
Code
Project
«
»
Cite
×